Generative AI Consulting Services
Trusted By Leading Enterprises



Years of Experience
Industries Mastered
Average Client Rating on Clutch
Average Reduction in Document-Heavy Workflow Time
Faster Pilot-to-Production Than Industry Average
GenAI Engineers & Solution Architects
AI Assessments & Roadmaps Delivered
Dextra Labs, A Generative AI Consulting Company
As an official OpenAI Select Partner, Dextra Labs is a generative AI consulting company whose consultants have hands-on experience building and deploying foundation models into production. Our approach begins with foundations of a reliable AI architecture that includes looking at where your data sits, how retrieval will behave against it, which model fits the latency and cost envelope, and who approves an output before it reaches a customer.
From there, we work across the components that make a production system function as a whole. We select foundation models across Claude, GPT, Gemini and open-weight options on evidence rather than preference, design retrieval augmented generation (RAG) pipelines on Pinecone, Weaviate or pgvector, and engineer the prompt, context and agent orchestration layers using LangGraph, CrewAI and AutoGen with MCP for structured tool access. Moreover, we fine-tune where it earns its cost against a measured baseline, and validate every system through evaluation frameworks such as Ragas rather than trusting that it works because it did well in the demo.
Once the system is live, the focus shifts to keeping it reliable under real workloads. Production brings its own challenges, from unexpected model behaviour to rising usage costs and stricter access requirements. Langfuse and LangSmith help make application behaviour visible, while runtime guardrails, access controls and cost governance provide the means to manage risks and resources. These are the controls that help an AI application remain manageable beyond launch, when reliability matters as much as functionality.

Delivery Hubs: USA, Singapore, India, UAE

Hallucination Rate on Governed Deployments

Production Uptime Across Deployed Systems

Tokens Processed in Production Monthly
5 Signs Your Business Need Generative AI Consulting
You don’t necessarily need generative AI consultants because you lack ideas. You may need them because your pilots aren’t progressing, your costs are unpredictable, or your teams can’t agree on the next step. Let’s have a look at five common signs that mean you need GenAI consulting services.
Your Pilot Works But Nobody Will Approve Production
Your demo went well, everyone saw the potential, and then things stalled. Two quarters later, you’re still waiting for someone to approve production. The problem often isn’t the model. It’s that you don’t have clear evaluation criteria, an agreed owner or a defined approval process. Our generative AI consultants help you put these pieces in place so you can move from a promising pilot to a system you’re ready to run in production.
Your Token Bill Is Growing Faster Than Your Usage
Your AI cost has outrun the forecast, you can't attribute it to a feature or a team. Unlike traditional software licences, inference costs depend on how your systems are used, and without a cost model, you can end up with an unpleasant surprise just a few months after launch. With the right generative AI consulting services, you can identify where model routing, caching and model tiering will help you control costs without compromising performance.
You Aren’t Sure Which Model To Standardise On
New models keep coming out, every team has its own favourite, and you’re worried that choosing one today could mean rebuilding everything six months from now. But you need to look beyond demo performance. Which model meets your accuracy, latency, cost and data residency requirements? Through enterprise generative AI consulting, you can build a system that lets you switch models without reworking your entire architecture, giving you the flexibility to adapt as better options emerge.
Compliance Came Up After the Build, Not Before
You were already well into development when your risk, legal or audit teams raised questions about data residency, retention or human review. Now, you’re facing architectural changes that could have been avoided if those requirements had been considered earlier. In regulated industries, retrofitting these controls can put the entire project at risk. Working with a generative AI consulting company that understands production requirements helps you account for compliance from the beginning, rather than scrambling to address it before launch.
A Competitor Just Shipped Something You're Still Debating
You’ve spent months discussing an AI use case, and now your competitor has launched something similar. You can’t afford to keep waiting, but rushing into production without the right data, evaluation or governance can create bigger problems later. With the right generative AI consulting services and solutions, you can focus on the use case that matters most, move quickly and build the foundations needed to make it work reliably beyond the demo.
Our Generative AI Consulting Services We Offer At Dextra Labs
At Dextra Labs, our generative AI consulting services help you turn
business challenges into production-ready AI solutions, from
strategy and model selection to integration, governance and continuous optimization.
Our generative AI strategy consulting helps you turn business priorities into a practical roadmap, starting with use cases that make sense in terms of value, data availability and technical feasibility. We assess potential initiatives, identify what needs to happen first, and separate the use cases you can tackle with retrieval-augmented generation (RAG) now from those that need better data or integrations. You come away with a prioritised roadmap, clear owners, measurable success criteria and a rationale for every decision, including the initiatives we recommend putting on hold.
Model and platform selection is a constraint problem, not a preference. We benchmark models as per your accuracy targets, latency budget, context-window needs, residency rules and cost per million tokens, comparing frontier options such as Claude Opus 5.5, GPT-5 and Gemini 2.5 Pro against open-weight models like Llama and Mistral you can host yourself. The output is a documented selection with the trade-offs written down, including what we ruled out and why.
Retrieval quality depends upon the data behind them, so our readiness assessment examines your data before we design anything on top of it. This covers data coverage, freshness, access control, chunking strategy, embedding model choice and the vector store that fits your needs, whether Pinecone, Weaviate or pgvector. You receive a clear readiness report for each use case, along with mentioning the gaps you need to address and the projects we recommend holding off on until the foundations are in place.
Our GenAI consulting work turns your selected architecture into a working system built around your data, retrieval patterns and real-world edge cases. We build the RAG pipeline, refine the prompt and context strategy, implement reranking and retrieval logic, build an evaluation harness using Ragas to measure performance, and also plan for fallback behaviour when a model provides something unusable. Plus, if fine-tuning provides measurable gains over your baseline, we’ll recommend it. Even if it doesn’t justify the cost, we’ll tell you that too.
We build a working prototype against your live data early, because testing with sample inputs tells you very little. Once the approach is validated, our generative AI integration services connect the system to your existing tools through APIs, event pipelines, webhooks and service boundaries so outputs land inside the CRM, ERP or support tools your teams already use rather than in a separate interface nobody opens. Moreover, we also define authentication, error handling, rate limits and rollback points before anything reaches a production release.
Where a general model cannot reach the accuracy, domain language or cost profile a use case needs, our custom LLM development builds the adapted version as per what your use case need, covering fine-tuning, LoRA and parameter-efficient methods, instruction tuning, distillation to a smaller model for cost or latency, and private or VPC deployment where data residency require it. Before recommending the custom model work, we quantify the gain against the general-model baseline first so you can measure whether this investment is worth making.
As per our years of experience at Dextra Labs, governance works best when it’s part of the design from day one. So, our generative AI governance work is designed into the architecture rather than audited onto it afterwards. We define model access policy, data usage boundaries, human-in-the-loop review thresholds, evaluation standards and audit logging, while implementing runtime controls for prompt injection, PII redaction and output filtering through Guardrails AI, NeMo Guardrails or Lakera Guard. Moreover, considering the industry and operating regions, our generative AI consultants ensure the EU AI Act, GDPR, HIPAA, India’s DPDP Act, ISO/IEC 42001 and UAE data protection requirements.
Getting your system live is just a beginning. A generative system’s response quality and performance can drift, as your business data, users, and needs keep evolving. Our LLMOps services help you keep track of how the system performs from the first deployment. We monitor response quality, retrieval precision, latency, token costs and output drift against the baseline captured before launch by using Langfuse or Langsmith. Then, we use these traces to identify where prompts, retrieval logic or model routing need adjustment. Over time, your teams will gain the visibility and confidence to make informed decisions, fine-tune performance and manage the system without relying on us for every change.
Our generative AI development services take a validated design and turn it into production-grade software. We build the application layer, orchestrate models and APIs using LangGraph, CrewAI or AutoGen, develop the backend services, and create agent workflows with MCP for structured tool access, all integrated to your existing data and identity system. If you need an engineering team to build and deploy the solution rather than just advise on the approach, our generative AI development services explains how we handle the build.
Our ChatGPT consulting services help you move beyond scattered individual use to a governed deployment on the GPT model family. We design the retrieval layer, system prompts, function-calling architecture and Assistants or Responses API integrations, along with the access and data controls your business needs. Plus, we also build an Org Brain context layer that connects ChatGPT to your organisation’s knowledge and business context, helping teams get more relevant answers grounded in the information they’re authorised to access. This way, you’ll receive more consistent, context-aware ChatGPT experience with the right controls and an audit trail, rather than a collection of browser tabs that everyone uses differently.
Build In-House, Buy a Platform, or Bring In a Partner?
AI TECHNOLOGIES
GenAI Models Powering Our Generative AI Consulting Services
Large Language Models
Natural Language Processing
Deep Learning
Computer Vision
Retrieval-Augmented Generation
Multimodal Models
Fine-Tuning & Model Adaptation
AutoML
Speech & Voice Models
Synthetic Data Generation
Small Language Models
Business Benefits of Generative AI Consulting Services
You find out what will not work before you fund it
The most expensive generative AI outcome is a well-built system solving a problem that did not need solving. Our gen ai consulting services start with scoring and readiness, which is the cheapest stage at which to kill a bad use case. Saying no in week two costs a fraction of saying it in month six.
Your architecture survives a model change
Provider capability and pricing have moved materially every few months for three years running, and nothing suggests that stops. Building the retrieval, orchestration and evaluation layers so the model underneath is swappable means a better or cheaper option becomes an upgrade rather than a rewrite. Systems that hard-code a provider age badly.
The cost model is understood before the bill arrives
Inference cost scales with usage in a way licence cost does not, and most overruns trace to architecture decisions made without a cost model. We forecast token spend per use case at production volume and design routing, caching and model tiering against it. You get a number you can budget rather than a surprise in month four.
Governance exists before the auditor asks
In regulated sectors the controls decide whether a system ships at all, and retrofitting residency, retention, human review and audit logging onto a live deployment is the most expensive rework on a generative programme. Designing those in during architecture costs a fraction of adding them later. It also shortens the approval cycle rather than extending it.
Improvement becomes measurable rather than anecdotal
A generative system without a baseline cannot be defended, because a model degrading slowly looks exactly like one working well. We measure the process before we touch it, then report against that same number afterwards through Langfuse or LangSmith. That reading is what lets your team argue for the next phase with evidence.
Your team can run it without us
An engagement that leaves your organisation dependent on the people who built the system has created a liability rather than a capability. We hand over runbooks, evaluation criteria, documentation and the reasoning behind each architectural decision. The measure of a good generative AI engagement is how little you need to call us afterwards.
Worried Generative AI Will Burn Budget With Nothing to Show?
Generative AI Consulting Tech Stack
We use the best tools in AI to build, connect, and deploy powerful agents that work for your business.

Claude (Opus, Sonnet)

GPT-6

Gemini 3.1 Pro

Llama

Mistral

Qwen

LangGraph

CrewAI

AutoGen

LangChain

MCP

Pinecone

Weaviate

pgvector

Cohere Rerank

Ragas

Langfuse

LangSmith

Guardrails AI

NeMo Guardrails

Lakera Guard

Deepgram

AssemblyAI

ElevenLabs

Cartesia

AWS Bedrock

Azure OpenAI

Google Vertex AI
Amazon SageMaker

On-Premise / VPC

Databricks

Snowflake

Apache Airflow

Kafka
Industries We Serve With Our Generative AI Consulting Services and Solutions
FinTech
Financial firms sit on more reviewable text than almost anyone, and most of it moves too slowly to be useful. In NVIDIA’s 2026 survey of over 800 financial services professionals, 89% reported AI had both raised revenue and cut costs, yet the gains only count when every output is auditable. Our generative AI consulting services build the systems that clear that bar, drafting credit memos, retrieving policy answers and turning regulatory change into reviewed briefs, each with a human sign-off before it reaches a customer or a regulator.
Retail and D2C
Catalog volume and customer-contact volume outgrow the teams handling them, long before anyone finds the budget to fix it. NVIDIA’s 2026 cross-industry study found retail and CPG leading every sector on savings, with 37% reporting cost reductions above 10%. We help retail and D2C teams capture that, generating product copy across large catalogues under brand control and deploying multilingual support that escalates anything sensitive rather than guessing.
Agriculture
Healthcare
Clinical documentation is the clearest generative use case in healthcare and the one with the least room for an unchecked answer. The American Medical Association reported in March 2026 that 81% of physicians now use AI professionally, up from 38% in 2023, and that 88% want robust safety validation first. That validation layer is what our generative AI consultants build, structuring clinical notes and drafting prior authorisations with clinician review designed into the architecture, not bolted on after.
Supply Chain
Supply chain teams lose their days reconciling exceptions across systems that do not talk to each other. Gartner’s May 2026 survey of 140 leaders found only 17% pursuing transformational redesign, with 83% stuck on isolated use cases, paced by data and process readiness. We start with that readiness, then build the generative layer on top, summarising exceptions across orders and shipments and answering network questions from contracts, SLAs and shipping records.
Insurance
Submission intake and claims handling are document-heavy, high-volume and slow, which is exactly where generation pays. Accenture’s study of 430 underwriting executives found AI touching 14% of underwriting work today, with 70% expected within three years, held back by systems and data access. We close that distance, extracting risk data at intake and drafting claims rationales with the explainability regulators and reinsurers require.
Manufacturing
Plant knowledge lives in manuals, maintenance logs and the heads of people approaching retirement. Deloitte’s 2025 survey of 600 manufacturers found generative AI already at 24% deployed and 38% in pilot, moving from pilot lines to plant networks. As your generative AI consulting company for the shop floor, we build the version that survives a plant audit, answering maintenance and procedure questions from your own technical library and generating work instructions and shift handovers.
E-Commerce
Product discovery is moving upstream of your storefront, into assistants that read catalogues rather than browse them. McKinsey reported in June 2026 that 38% of European consumers now use generative AI to research products and decide what to buy. We help e-commerce teams stay visible inside that shift, structuring product data so AI assistants can read and recommend it, and deploying conversational shopping grounded in live inventory and policy.
Real Estate
Lease abstraction, valuation and portfolio reporting are document-synthesis work that still eats analyst weeks. JLL’s 2025 survey of over 1,500 decision-makers found 88% of owners running AI pilots but only 5% meeting every goal they set. Closing that pilot-to-programme gap is what our generative AI consulting services do here, abstracting leases at portfolio scale and generating reporting straight from the underlying records.
Technology and SaaS
Software teams are now building what they used to buy, and shipping generative features their own customers expect. McKinsey’s 2026 survey of 1,719 respondents found 32% had skipped buying a product because agentic tools let them build it in-house. Our gen AI consulting works both sides of that, shipping features with evaluation harnesses in place from day one and giving a straight answer on what is genuinely worth building versus buying.
Energy and Utilities
Grid and asset operations drown in telemetry, procedure and regulatory reporting, and the reporting half is where generation earns its place first. The International Energy Agency estimates AI management could unlock up to 175 gigawatts from existing transmission lines and cut outages by 30% to 50%. We build into live operational environments where the latency budget is set by the decision, automating compliance reporting and summarising network telemetry into operator-ready briefings.
What Makes Dextra Labs the Best Generative AI Consulting Company
in USA, Singapore, India and UAE?
We bring the engineering depth and practical judgement businesses need from a generative AI consulting company to turn complex requirements into reliable, production-ready systems.
An Official OpenAI Select Partner That Stays Model-Agnostic
Dextra Labs holds the OpenAI Select Partnership that proves real depth on the biggest platform, and still picks the model on your constraints rather than our allegiances. Our generative AI consultants benchmark Claude, GPT-6 and Gemini against your accuracy, latency and cost thresholds, then build so the choice stays swappable when a better one ships. You get the credential and the honest recommendation, which is rarer than either on its own.
We Tell You When You Don’t Need Us
We would rather lose the engagement than sell you a build you do not need. Some use cases are solved faster and cheaper by a forecasting model, a search index or plain rules, and you will hear that on the first call rather than in month three. Naming the boundary costs us the project and earns us the trust, which is the trade a generative AI consulting company should be willing to make.
We Put A Named Engineer On Your Call, Not An Account Manager
Other firms will give you an account manager who relays your questions to a team you never meet. Dextra Labs puts you with the engineer who understands your architecture and will actually build it, from the first call onward. There is no handoff after signing, because the person who scoped the work is the person who owns it.
We Scope To A 30-Day Proof, Not A 12-Month Commitment
We start with one use case, a fixed price and a month, not a year-long programme you have to approve on faith. In thirty days you get a working prototype running on your own data, a measured baseline against your current process, and a written go or no-go recommendation that includes the honest version if the answer is no. You own everything we produce either way, and you commit to the full programme only once the proof has earned it.
We Put Governance In The First Sprint, Not The Last
Most firms treat governance as a review stage at the end. Dextra Labs makes it a priority from day one, designing residency, retention, human review and audit logging into the architecture before any code ships. Retrofitting those controls onto a live system is the most expensive rework on a generative AI project, so building them in early means our generative AI consulting services clear your approvals faster rather than stalling on them.
We Show You The Running Cost Before You Commit
Inference cost is where generative AI budgets quietly break, usually around month four, because the architecture was designed with no cost model behind it. At Dextra Labs, we forecast your token spend at real production volume up front, then designs routing, caching and model tiering against that number. You approve a figure you can plan around, not one you discover on an invoice.
Not Ready to Commit to a 12-Month Programme?
Our Comprehensive Generative AI Consulting Process
Score the use cases
We start with the metric your leadership already cares about and work backwards to where generation could move it. Candidate use cases are scored on business value, data availability, technical feasibility and the visibility of the improvement. You finish this stage with a ranked shortlist and a written reason for every case we recommend dropping.
Test data and platform readiness
Retrieval quality is capped by the corpus underneath it, so we assess coverage, freshness, access control and structure before designing anything. This stage also captures the baseline measurement that every later claim about improvement will be judged against. It is designed to surface blockers early and to say no when the data cannot support the use case.
Select the model and architecture
With constraints established we test candidate models against your real accuracy, latency, residency and cost thresholds rather than against a benchmark table. The architecture decision covers retrieval strategy, chunking, embedding approach, orchestration and whether fine-tuning earns its cost against the general-model baseline. We document what we ruled out alongside what we chose.
Design governance into the build
Approval workflows, access controls, human review thresholds, evaluation standards and runtime guardrails are defined before development begins. Depending on sector and geography this covers the EU AI Act, GDPR, HIPAA, India's DPDP Act, ISO/IEC 42001 and UAE requirements. Governance added after a system is live is the most expensive rework on a generative programme.
Build and integrate
Implementation runs through controlled engineering milestones with rollback points defined before any release goes live. We connect retrieval, models and orchestration to your existing applications, data platforms and identity systems so outputs arrive where the work already happens. This keeps delivery measurable and keeps critical workflows out of harm's way.
Validate against the thresholds
The system is evaluated against the criteria agreed in step two, not against an impression formed after launch. Testing covers accuracy, retrieval quality, response behaviour, latency, cost per outcome and failure modes under unusual input. Measuring against a pre-agreed number is what makes the improvement arguable rather than anecdotal.
Hand over and keep measuring
We support the production release alongside runbooks, evaluation documentation and knowledge transfer, then instrument the system for drift, quality, latency and cost. Your team learns to read those signals and act on them. The goal is that you run and extend the system without calling us for every decision.
Meet the Senior Generative AI Consultants Behind Our Work
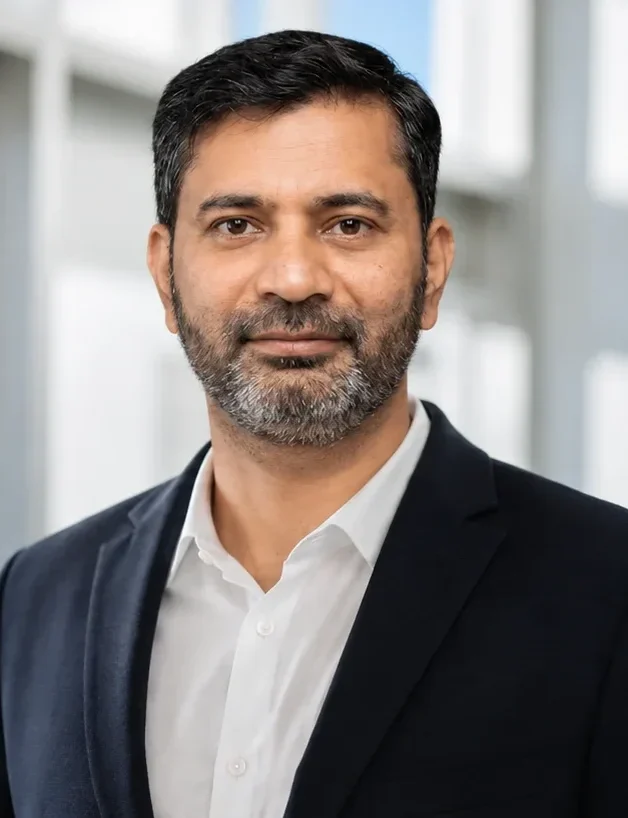
Abhinav Srivastava
- AI Solutions Specialist, Machine Learning, Dextra Labs
Abhinav has spent around twelve years building AI and machine learning systems that run in production, which is a different discipline from building ones that demo well. He leads engagements where the business case has to survive a finance review, working backwards from the number you need to move rather than forwards from the technology available. On most engagements he runs the cost model before anyone writes code, and he says so plainly when the payback does not hold. Clients tend to keep him on the call when the CFO joins.
- Ask for Abhinav when your board wants a defensible number before it approves a generative AI budget
- He will answer whether the use case pays back, what inference costs at production volume, and how long before it clears
- In the first three weeks you get a scored use case shortlist and a cost model your finance team can audit line by line
- Best fit for lending, insurance, energy and retail, where decisions are high volume and the impact is countable
- He will push back if your data cannot support the accuracy your business case assumes

Mudassar Pasha
- Senior Consultant, Enterprise AI Delivery, Dextra Labs
Mudassar has spent around seventeen years inside enterprise transformation programmes, where the technology is rarely the part that decides the outcome. He runs delivery on engagements crossing several systems and several stakeholder groups, setting the sequence, the governance and the escalation path before the first sprint rather than after the first delay. As a credentialed trainer he also owns the capability side of an engagement, so your teams can carry the system once it is handed over. He has seen how programmes stall and designs around it in advance.
- Ask for Mudassar when the distance between approval and production runs through several teams and systems
- He will answer who needs to sign off, in what order, and where the programme is most likely to slow
- In the first month you get a phased roadmap with named owners, decision gates and a working escalation path
- Best fit for enterprises with legacy estates, multiple business units, or a regulated approval chain
- He will push back if the sequence puts an integration ahead of the data work it depends on
Compliance and Security Standards Our Generative AI Work Meets
Frequently Asked Questions
What is Generative AI Consulting?
What is the difference between generative AI consulting and generative AI development?
Consulting decides what to build, which model fits and whether the data supports it. Development builds the system once those decisions are made. Most engagements need both, and our generative AI development services page covers the build side where a project needs engineering rather than advisory.
How much do generative AI consulting services cost?
Generative AI consulting costs depend on data condition, integration surface, regulatory load and who maintains the system afterwards. Our bands cover readiness assessments, strategy engagements, a 30-day proof of value, production pilots, full implementations and managed optimisation. Every band is a fixed-scope price, listed above on this page.
How long does a generative AI consulting engagement take?
A readiness assessment takes 2 to 4 weeks and strategy work 3 to 5. The 30-day proof of value runs 4 weeks. A production pilot takes 6 to 10 weeks, a full implementation 8 to 16. Regulated environments and multi-system integrations sit at the top of each range.
How do I choose a generative AI consulting partner?
Check four things: whether they own delivery or hand off after the recommendation, whether they name the consultants on your engagement, whether production references exist, and how they handle your data and model keys. Ask who signs off on accuracy and what happens when the model is wrong.
Do I actually need generative AI consulting?
Not always. A single well-scoped drafting or summarising task on clean data your team already owns is often faster built in-house. Generative AI consultants earn their cost when the work crosses systems, touches regulated data, needs an audit trail, or has to keep running after the builders leave.
Which generative AI model should an enterprise use?
No single model wins across every use case, which is why we test candidates against your accuracy, latency, residency and cost thresholds rather than a benchmark table. Claude, GPT and Gemini each lead on different axes. We build so the model stays swappable without rewriting the system.
How do you stop a generative AI system giving wrong answers?
Wrong answers are usually a retrieval problem rather than a model problem. We ground outputs in your own documents, score retrieval quality with Ragas, add runtime controls through Guardrails AI or NeMo Guardrails, and route anything below a confidence threshold to a human. Evaluation runs continuously, not once.
Where can I find generative AI consultants near me?
We deliver from Singapore, India, the United Arab Emirates and the United States, with consultants staffed to your business hours rather than ours. Our headquarters is at 20 Cecil Street, Singapore. We also deliver for clients across the United Kingdom and Europe from our Singapore and India teams.
Which industries benefit most from generative AI consulting?
Financial services, supply chain, manufacturing, healthcare, retail and agriculture carry the clearest returns, because each runs high volumes of document and language work that already exists in written form. We hold case studies in renewable energy forecasting, lending and underwriting, and multilingual customer service for D2C retail.